About Me
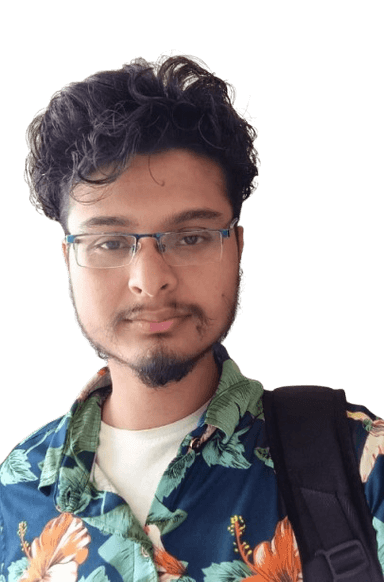
Bibek Dhakal
I'm an entry-level AI / ML engineer with a software engineering background. My evidence is a ML internship, an ML apprenticeship, several projects with public code, and earlier software work. I'm not claiming years of production ML ownership. I'm looking for a team where I can contribute to real systems and grow over the long term.
ML internship at FlyRank AI (Jul–Sep 2026), ML apprenticeship at Skill Shikshya, and earlier software engineering roles. Based in Kathmandu, Nepal.
What I work on
Applied ML & evaluation
Framing a problem, choosing an honest validation design, and comparing against simple baselines.
- TabTrace: Reproducible pipeline that halts on data leakage, registers feature rationale in code, and evaluates via stratified cross-validation.
- FlyRank capstone: client-holdout split, baseline rule vs. Logistic Regression vs. Random Forest, and two deliberately planted leaks to test the validation.
- Churn model: 5-fold stratified CV; logistic regression (0.8501 ROC-AUC) beat Random Forest and LightGBM.
- Phishing detector: XGBoost with Platt-scaled probabilities and soft-voting fusion across two feature sources.
- OverfitLab: Demonstrated the diagnosis of train/val divergence and corrected it with Dropout and Weight Decay on a PyTorch MLP.
ML services & MLOps
Turning a model into something that runs, is validated at its edges, and can be released repeatably.
- ModelGate: Containerized FastAPI inference service featuring dynamic URL model loading, strict JSON schema validation, and error shielding.
- Churn pipeline: Pandera and Pydantic data contracts, MLflow experiment tracking, Skops serialization, Dockerized FastAPI service.
- CI/CD with GitHub Actions, Pytest, Ruff, and Release Please across TabTrace, ModelGate, and Churn projects.
- FastAPI with Docker or Docker Compose across the churn, phishing, and Forge-LM projects.
LLM & inference fundamentals
Learning-scale implementations that show how the pieces work, plus a lightweight RAG agent.
- LexiByte: BPE tokenizer written from scratch and published on PyPI.
- NanoTransformer and Forge-LM: GPT-2-style decoder in PyTorch, ~28M parameters trained on TinyStories, exported to INT8 ONNX and served on CPU.
- Aegis: ReAct-style RAG agent using FAISS and INT8 ONNX inference, designed for limited memory.
Software engineering
Internships and contract jobs (2023–2025) building the apps and backends for various projects.
- AcademiaOS MVP: FastAPI and Celery backend, Next.js frontend, HTTP-only cookie auth and RBAC.
- Flutter, React, and Next.js work across several companies, including support for a Google Play Store launch.
How I work
Baseline before model
I write down a simple, transparent rule or linear model first, then make the fancier model earn its place. In both my churn project and TabTrace pipeline, logistic regression beat the tree ensembles. In my FlyRank capstone the hand-written rule scored 0.260 Precision@50 on unseen clients, slightly below chance (0.286), which made the model's 0.640 a real result.
Suspect the split first
A convenient split flatters a model. My capstone's random split scored 0.940 Precision@50; holding out whole clients gave 0.640. I split by group, keep label components out of the features, and build tools like TabTrace that enforce deterministic, saved splits with strict leakage checks.
Build the whole path
A model is only useful if something can call it, and reproducible if its pipeline is tested. I unit-test preprocessing logic (TabTrace), validate data at the edges (ModelGate, Pandera), track experiments, containerize the service, and automate tests and releases.
Say what it isn't
Each project states its limits: observational data, learning-scale training, a proxy label. Someone else can then judge what the work does and doesn't show.
Toolkit
Languages
- Python
- TypeScript
- SQL
- C#
- Dart
ML & AI
- PyTorch
- TensorFlow
- Scikit-learn
- XGBoost
- NumPy
- Pandas
- OpenCV
- Hugging Face
LLM & inference
- Transformers
- BPE tokenization
- RAG / FAISS
- ONNX Runtime
- INT8 quantization
- FlashAttention
Data
- DuckDB
- BigQuery
- PostgreSQL
- Redis
Backend & MLOps
- FastAPI
- Docker
- Celery
- MLflow
- Pandera / Pydantic
- GitHub Actions
- WebSockets
Apps
- React
- Next.js
- Tailwind CSS
- Streamlit
- Flutter
Background & availability
Before moving into ML I worked as a software engineer (Flutter, React, Next.js, FastAPI) through internships and contracts from 2023 to 2025, so I'm comfortable shipping the backend and app code around a model, not only the notebook.
Available immediately. My degree exams and internship are finished, and new projects go on GitHub.